Draft from four languages
Write rules in English, French, German, or Spanish, in Decision or Argument mode. Ambiguity comes back as concrete choices: for “A or B and C” you see (A OR B) AND C, A OR (B AND C), and a case where they differ.
Features
Author in words, formulas, or diagrams, over Boolean inputs, numbers, categories, scales, counts, and scores. Check every case exactly. Explain it in plain language, test it like code, keep its full history, export it to the tools your team already uses, and build on it through the API.
Author
Every view edits the same typed model, so the plain-English source, the formula, and the gate diagram can never quietly drift apart. Move a gate and only the layout changes; rename an input and every reference follows.
Starting from words? Describe the rule and AI drafts a formula, a glossary, and the questions it couldn’t settle. The draft stays unconfirmed until you say it means what you meant.
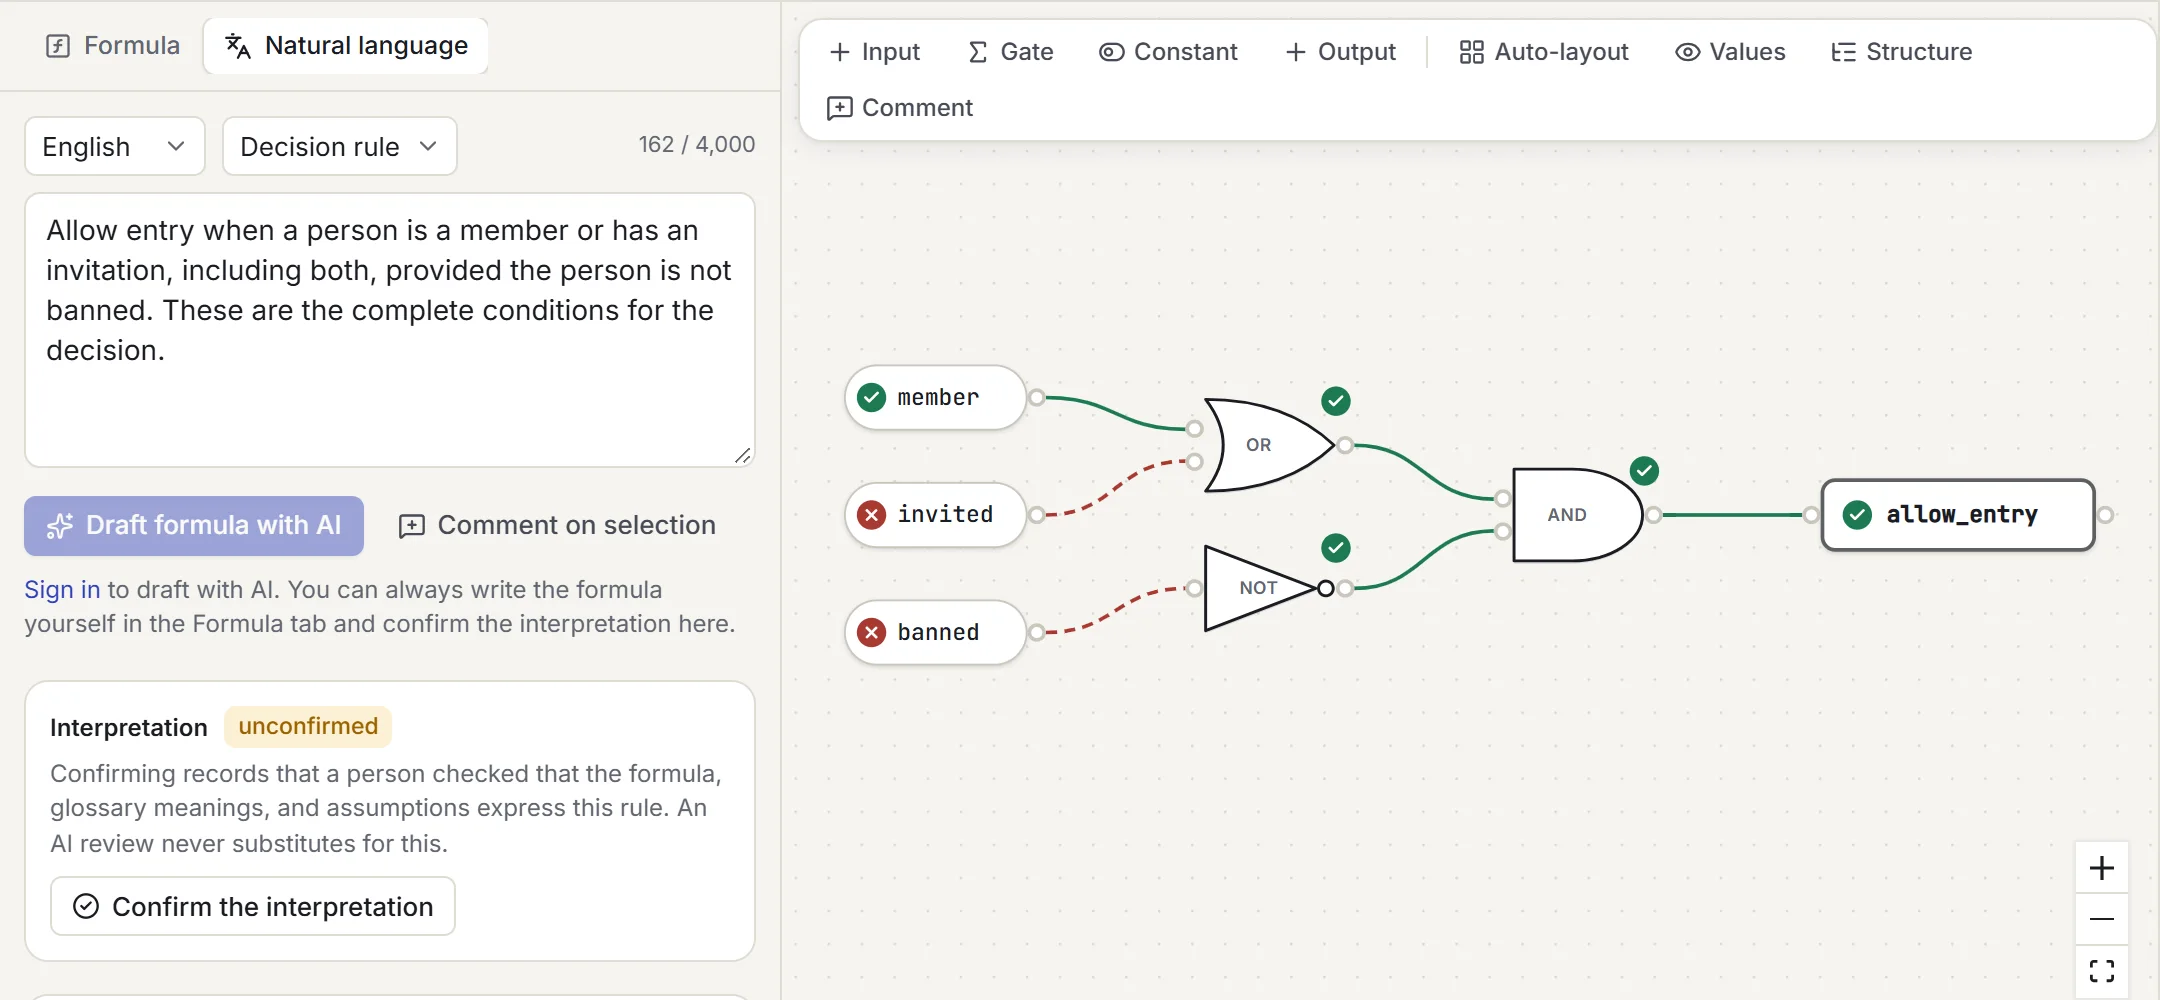
Write rules in English, French, German, or Spanish, in Decision or Argument mode. Ambiguity comes back as concrete choices: for “A or B and C” you see (A OR B) AND C, A OR (B AND C), and a case where they differ.
Programming (AND, &&, !), mathematical (∧ ∨ ¬ → ↔), or textbook (A·B, A+B, overbars, indexed minterms). They all compile to the same model, and AB is always one name, never a hidden AND.
Inputs, constants, and every supported gate, with labelled ports, zoom, pan, and auto-layout. A keyboard-operable structure view sits alongside, so nothing depends on dragging.
Give every input a human meaning, and state constraints explicitly. Tangibool never assumes that “premium member” implies “member” unless you add that assumption yourself.
Save a selection as a named, versioned subcircuit with typed ports. Each instance is pinned to a version and never upgrades silently; expand it to see the values inside. Keep libraries for yourself or your team.
Undo and redo everywhere. An invalid draft never overwrites your last valid model: it stays visible, clearly labelled as the previous valid revision, until you fix the errors in your current text.
Rules depend on ages, amounts, plans, countries, ratings, counts, and scores. Define each one outside the formula, and Tangibool compiles it to TRUE/FALSE inputs with the facts between them derived exactly and labelled as derived, so every check stays two-valued and every result stays exact.
“Age is at least 18” becomes the threshold input age_at_least_18, defined as age ≥ 18 on a whole-number or decimal quantity. Type a comparison into a formula and the editor offers the definition. Give a number in a scenario and every threshold on that quantity is decided by exact comparison, with the ordering between thresholds derived for you: anyone aged 25 or more is aged 21 or more.
Define plan with Free, Basic, Pro, and Team, or country with ISO codes, and name lists of values: EEA, Paid plans, or a union, intersection, or difference of other lists. A category input holds one value, a set-valued input holds any subset, and formulas test membership with plan IN Paid or activities HAS NONE Excluded. Facts such as “every collaborative plan is paid” are derived from the lists, never guessed. Two or three lists of a category are drawn as a Venn diagram with the values in each region, and lists that name a parent list appear as a tree.
Credit ratings, risk classes, customer tiers: a scale lists its levels from lowest to highest, plus outside values such as Not rated that satisfy no comparison. rating ≥ BBB- gets neighbouring-level boundaries and boundary tests, a comparison input relates two quantities on one scale, and a mapping between two scales must preserve order and is a versioned resource that you confirm. The mapping is drawn as arrows between the two scales, with the levels that share a target and the levels left untranslated listed under it.
“At least two of three criteria” is a count, not a chain of XOR. AT_LEAST(k; …), AT_MOST(k; …), and EXACTLY(k; …) take two or more conditions and appear as one gate in the diagram, with the literal reading “at least 2 of …” and boundary cases at k−1, k, and k+1 conditions.
A score adds up the points of the rows whose condition holds, and score thresholds such as score_at_least_5 are inputs that your formulas use by name. The evaluation trace lists each row’s contribution and the total, the score range is shown, and a cutoff outside that range is flagged as a constant.
A decision can have more than two outcomes: Approve, Refer, Decline. Define them as one condition per outcome, as a rule list where the first match wins, or as a decision table with the hit policy Unique, Any, First, or Priority. Formulas read an outcome like a category: preapproval IN {Approve, Refer}.
Check
Ask a precise question and get a precise answer: holds or doesn’t, with the assignment that proves it. Every result states the property checked, the assumptions, the method, and the revision it applies to.
Can this be true? Is it always true? Can it ever be false? Are these two equivalent? Does the conclusion follow? Is this rule at least as strict as that one? Does every case get exactly one outcome? Each is a precise satisfiability query, not a guess.
Every counterexample and witness is re-run in the evaluator before it’s shown. Load it into the simulation or save it as a regression test in one click.
Assumptions are tested for consistency before anything else. An impossible set of assumptions can never produce an “all tests pass” or “equivalent” badge.
State premises and a conclusion. Get “valid”, or the assignment where every premise holds and the conclusion fails. Premises that contradict each other get a prominent warning, not a hollow success.
See whether each input can change a result, proved with two assignments that differ only in that input. Find out whether a premise already follows from the others.
When assumptions or premises can’t all hold, Tangibool returns a checked conflicting subset mapped back to your original clauses, and says plainly what wasn’t tested.
For an output or an outcome, see the necessary conditions that every qualifying case shares, the ways to qualify, each a set of facts that guarantees the result with nothing removable, fewest facts first, an irreducible reason for one case, and the smallest changes to the inputs you allow to change that give a different result. Every fact replays, and a list is called complete only when the engine has shown it is.
Compare two rules, two revisions, or two branches: at least as strict, equivalent, looser, or incomparable, with a replayed case for each direction that fails. Draw a strictness map for up to twelve rules, declare rule layers such as regulation, prospectus, mandate, and internal limit and check each against the one above it, and state that raising an input never turns a result from TRUE to FALSE. Every answer is exact, and each runs as a property test.
An outcome set is checked for completeness and exclusivity: every admissible case gets an outcome, and no case gets two. Gaps, overlaps, and rows that can never apply are reported with replayed cases and never repaired behind your back, and a table with a gap or an overlap exports only as a labelled draft.
The map of up to twelve rules is a drawing as well as a list. Looser rules sit above stricter ones, a line joins neighbours, and rules with no path between them are incomparable. Select a line to open the replayed case that the looser rule allows and the stricter one does not.
Pick two or three rules and see which combinations can happen. The engine decides each region exactly: it holds a replayed case, or it is hatched and labelled empty. Under the drawing, in words: equivalent, at least as strict, never both TRUE, or every case has one of them.
A drawing is a view of a result, never a result of its own. A pair or a region the engine could not decide is labelled Not determined, never drawn as unrelated or empty. Every drawing has a text form beside it for keyboards and screen readers, and no status rests on colour alone.
Small models are checked over every assignment in your browser and cross-checked by a SAT solver. Larger ones use a bounded solver query on the server, with a two-second default budget, and only after you agree to send the model. Analyses that need many queries, such as the ways to qualify or a strictness map, share a ten-second budget and are labelled partial when it runs out.
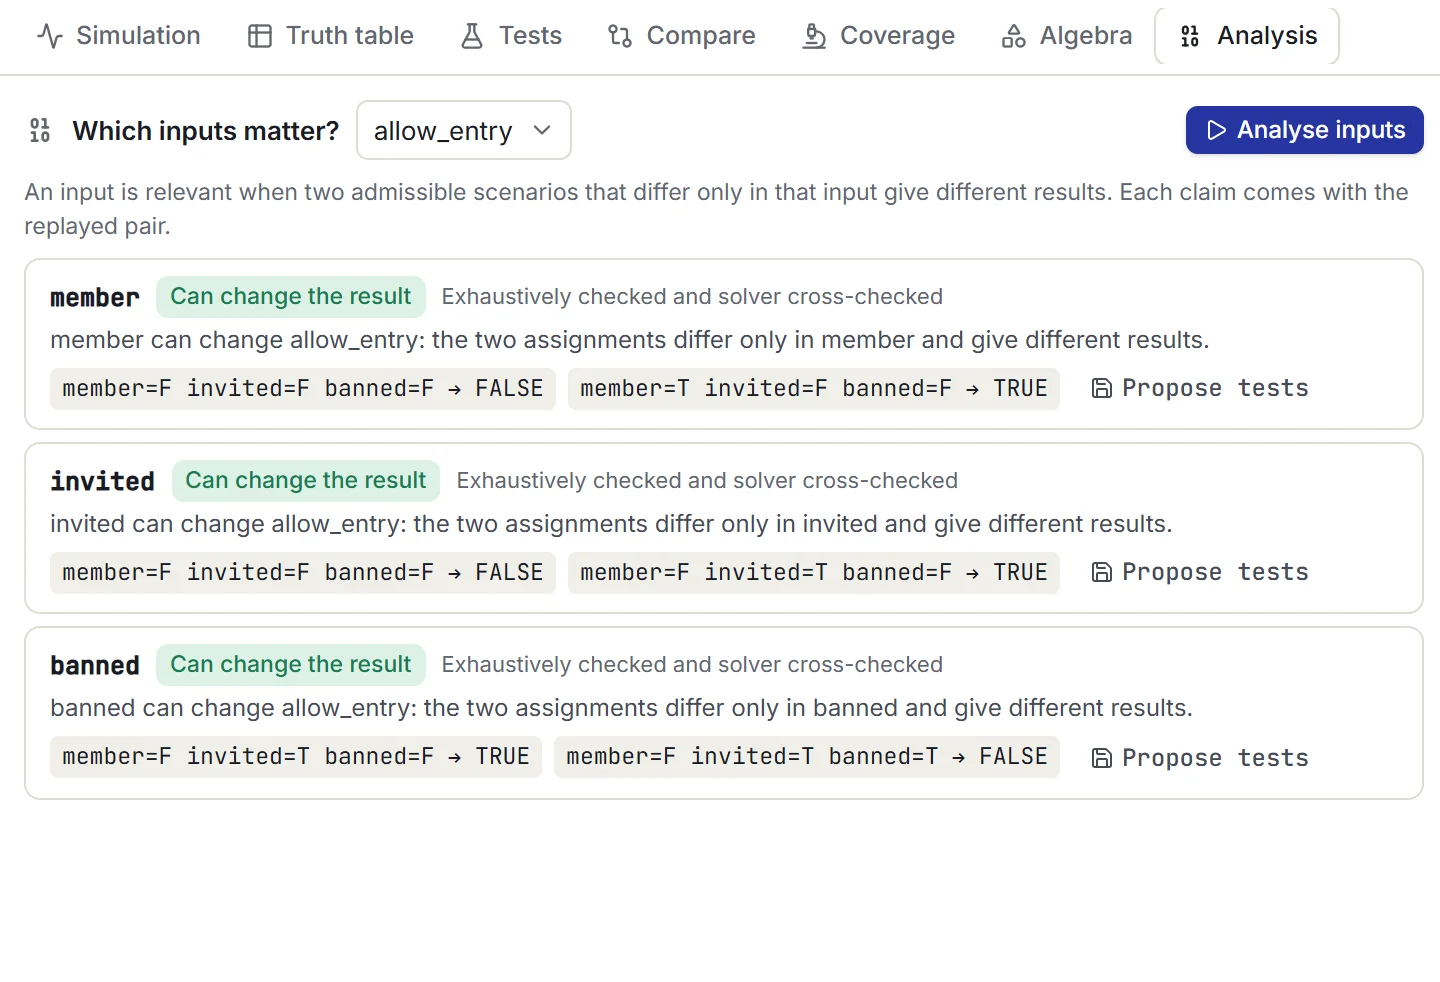
Explain
Every formula gets a literal reading generated by the engine, not by AI, so it is exactly as precise as the logic. Toggle a scenario and an evaluation trace explains why each gate is TRUE or FALSE.
allow_entry is true exactly when both of the following hold:
member (“the person is a member”) or invited (“the person has an invitation”) is true (both may be true)banned (“the person is banned”) is falseIn every other case, allow_entry is false.
Why · evaluation trace
Test
Simulate scenarios, see the complete truth table, save tests with their provenance, and find out how good those tests really are. Then run the same suite in continuous integration.
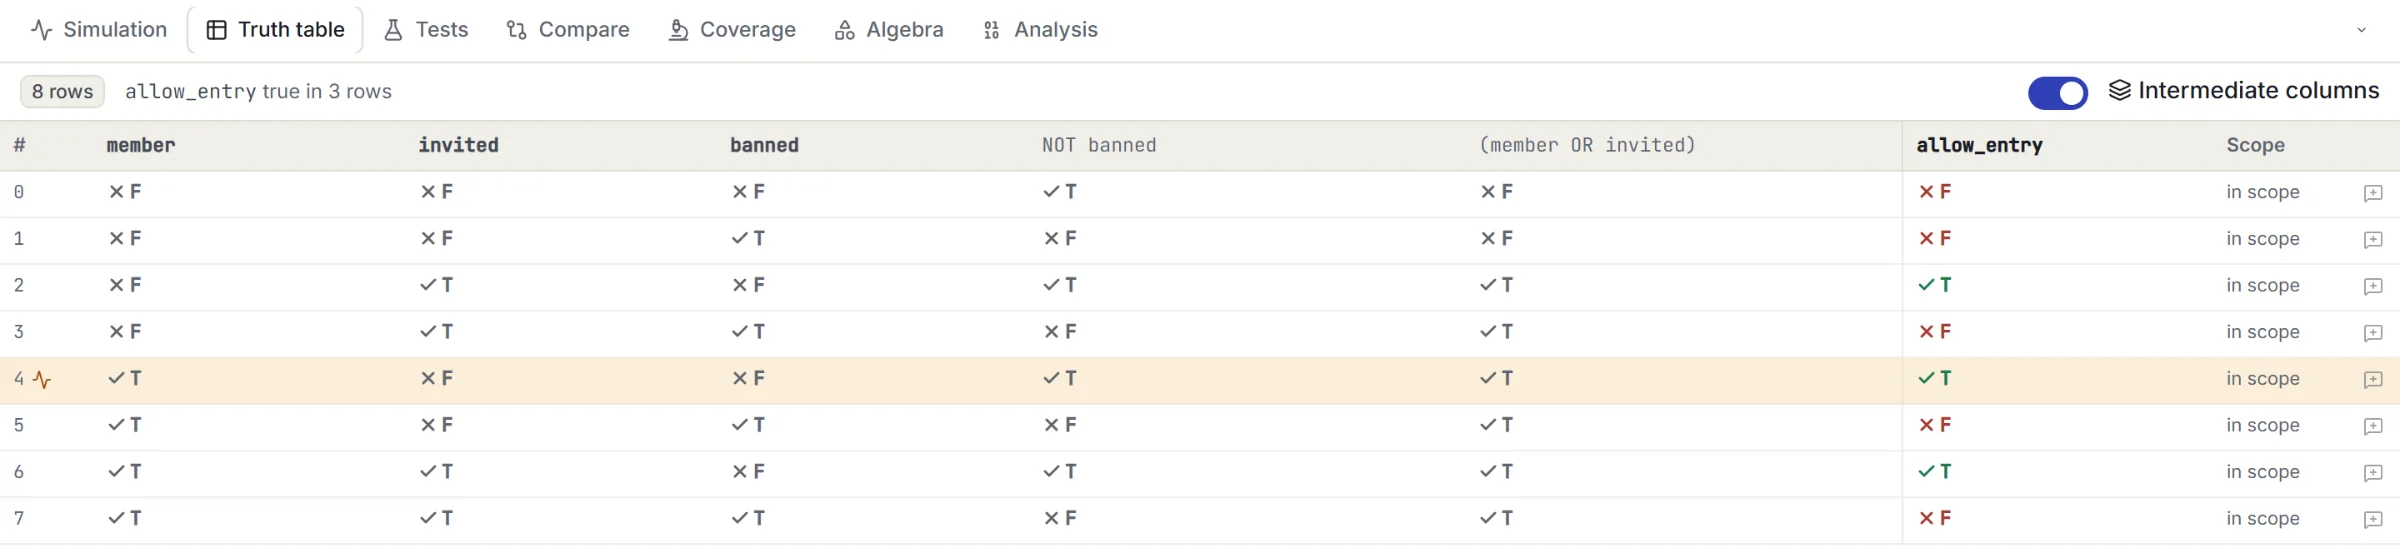
Toggle inputs and watch values flow through the diagram. Give a number, a level, a value, or a set and every test on that quantity is decided by exact comparison. An input you haven’t set has no value and is never quietly treated as FALSE.
Save scenario and property tests with notes. A scenario can expect an outcome label, and a different label fails naming the deciding row or condition. Each expectation records where it came from: Independent when a person confirmed it, Exploratory when it was copied from the formula itself.
Rerun after every edit. Results from older revisions are marked stale, newly failing tests are called out, and the failing path is traced on the diagram.
Input-value, gate-output, and decision-outcome coverage, then category classes, counting boundaries, outcome labels, and decision-table rows, plus input influence shown by paired scenarios. Every metric publishes its denominator, and unreachable classes and rows are excluded and listed. Where a category has two or three membership tests, its value classes are marked covered or not covered on a Venn diagram.
Up to 500 seeded single-edit mutants: AND↔OR swaps, negations, substitutions, and removed clauses, and for the richer inputs a moved threshold or cutoff, a changed count, a list member moved, a changed weight, or a removed or reordered row. Equivalent mutants are found by exact comparison, and the score never hides what it excluded.
The tangibool command runs the same engine on an exported package, or on a cloud model that it reads through the API with a token, and writes JSON and JUnit reports. Exit code 0 only when at least one applicable test ran and all of them passed.
Tangibool proposes boundary tests either side of a threshold or a score cutoff, and class tests, one scenario per class of category values that the logic treats alike. Coverage reports whether each count was seen with k−1, k, and k+1 conditions. Every proposal is exploratory until you confirm it.
“At least as strict as” and “raising this input never turns the result from TRUE to FALSE” are saved as property tests with the statuses pass, fail, vacuous, and not determined. They run in suites, in the browser, and in the headless runner.
A saved test keeps the number, level, value, or set you gave, so editing a list or a threshold changes what the test checks, marks earlier results stale, and shows up in the behaviour comparison with a witness that gives a value.
Mutation testing makes small deliberate mistakes in your rule and checks whether your saved tests notice. A surviving mutant comes with the scenario that tells it apart, ready to become your next test.
The score is killed ÷ (killed + surviving). Equivalent, invalid, out-of-scope, and undetermined mutants are shown separately, and an empty denominator is never reported as 100%.
tangibool test model.json --revision main \
  --junit reports/tangibool.xml --json reports/tangibool.json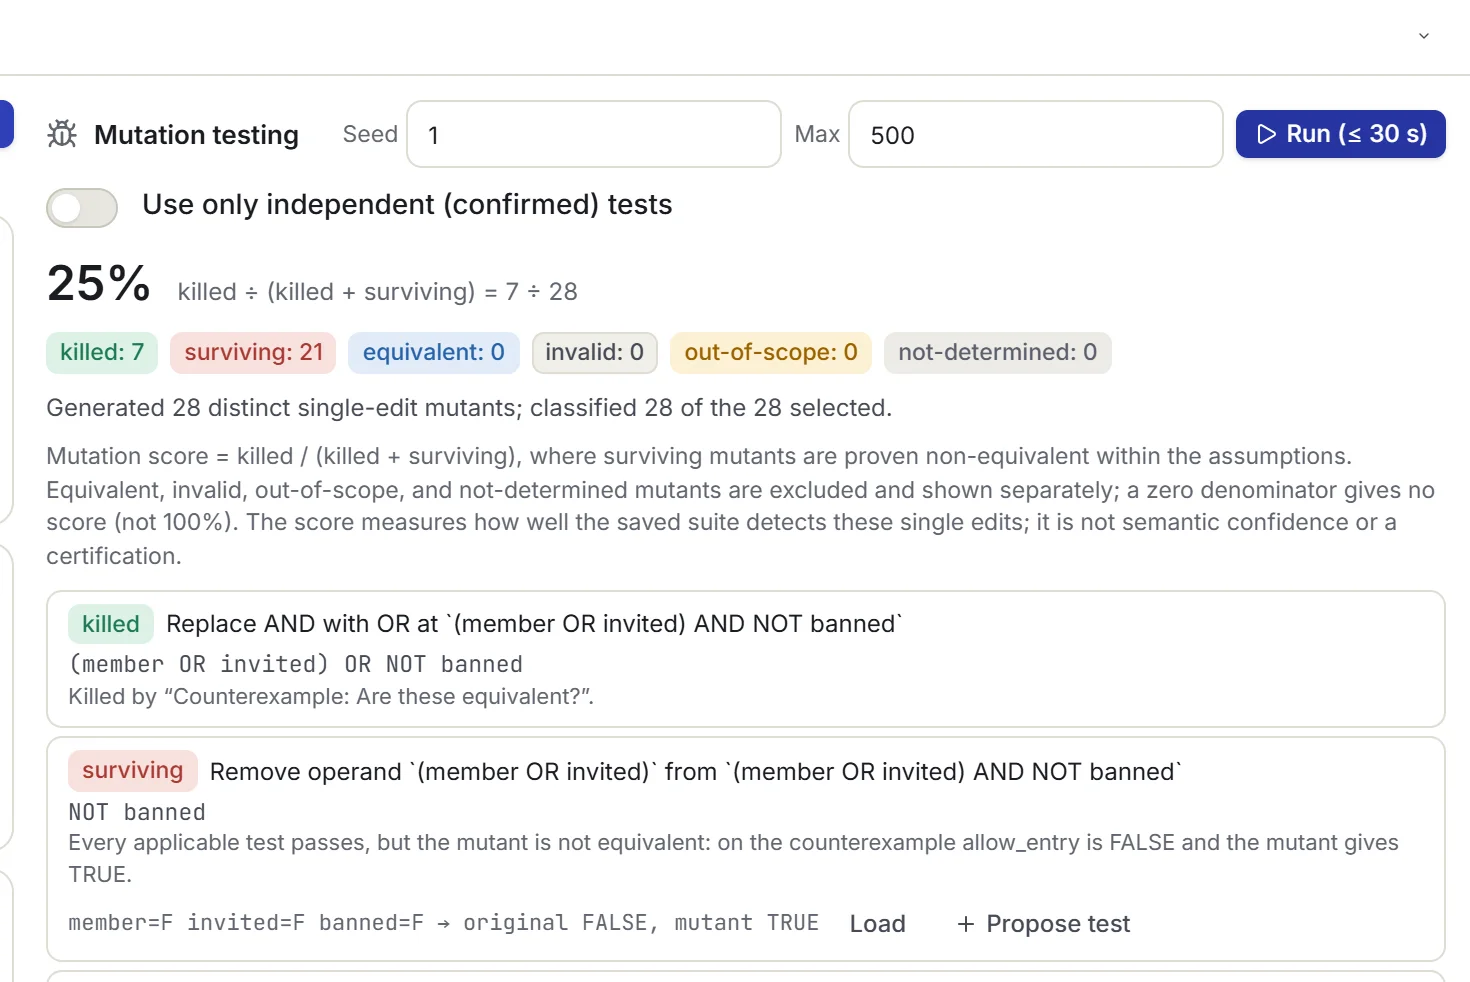
Algebra
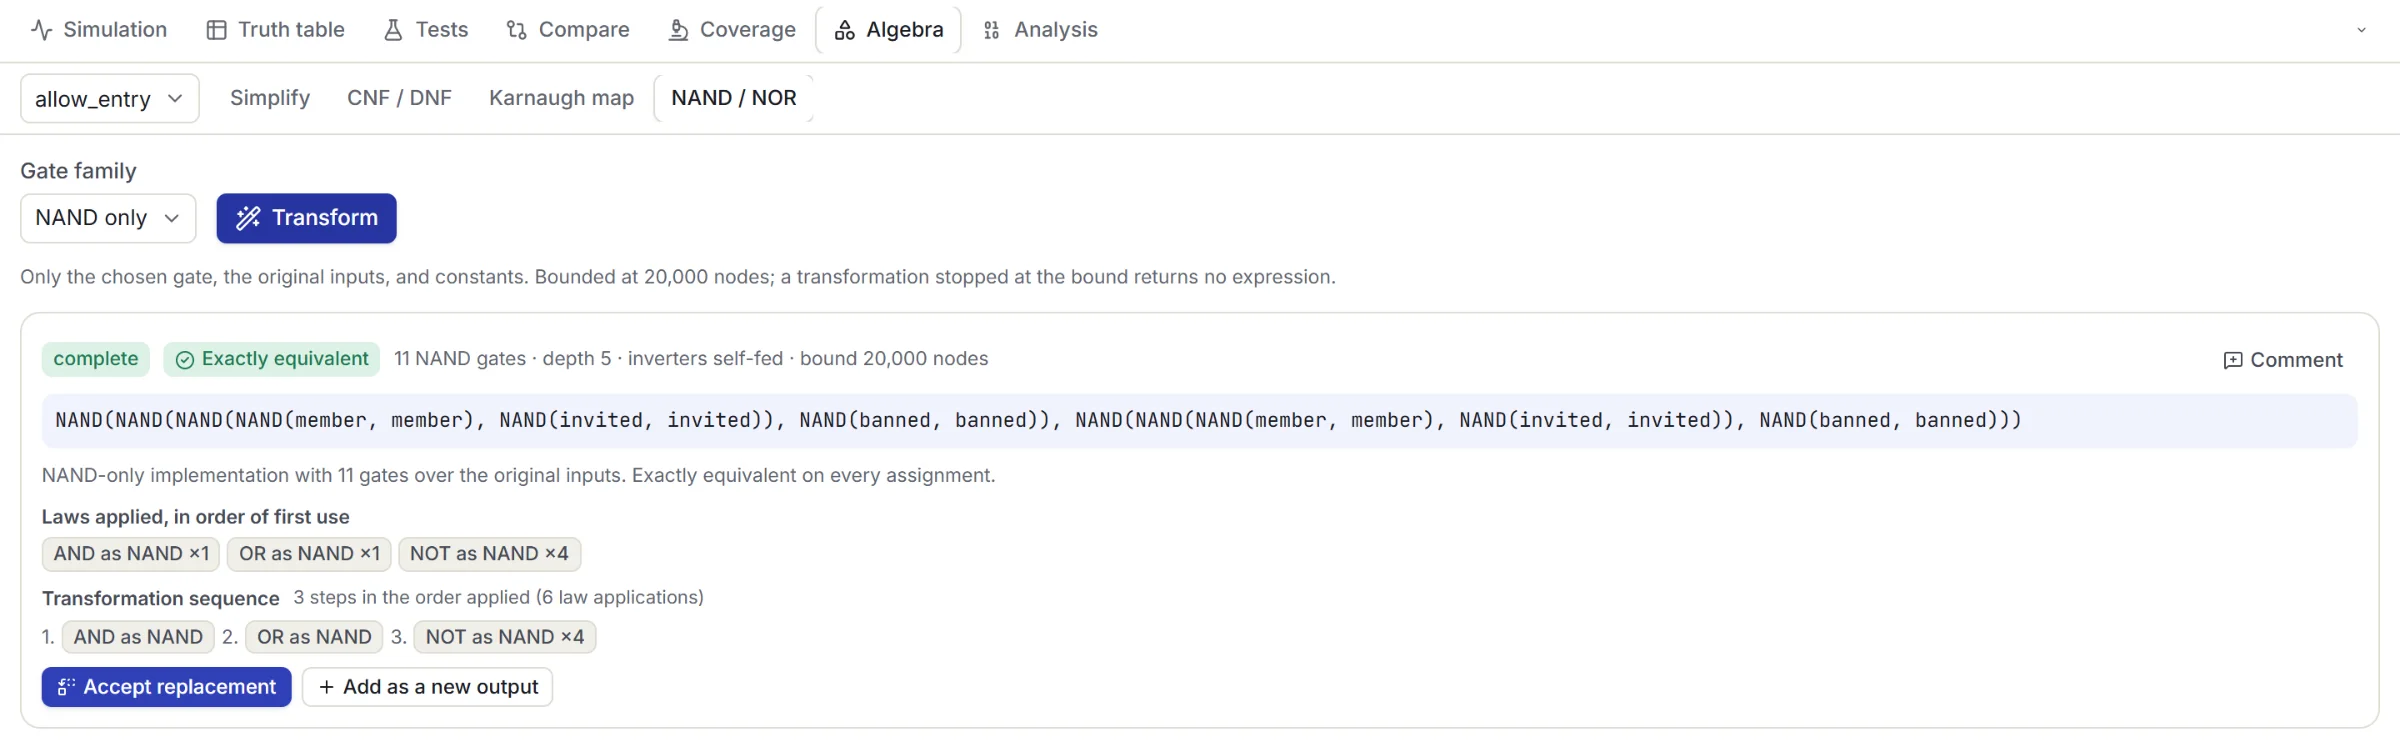
Every transformation shows its scope, size, and an exact equivalence result before you accept it. Your original stays editable until you choose the replacement.
count-expansion, within the same bounds. Score thresholds stay references and expand only on request.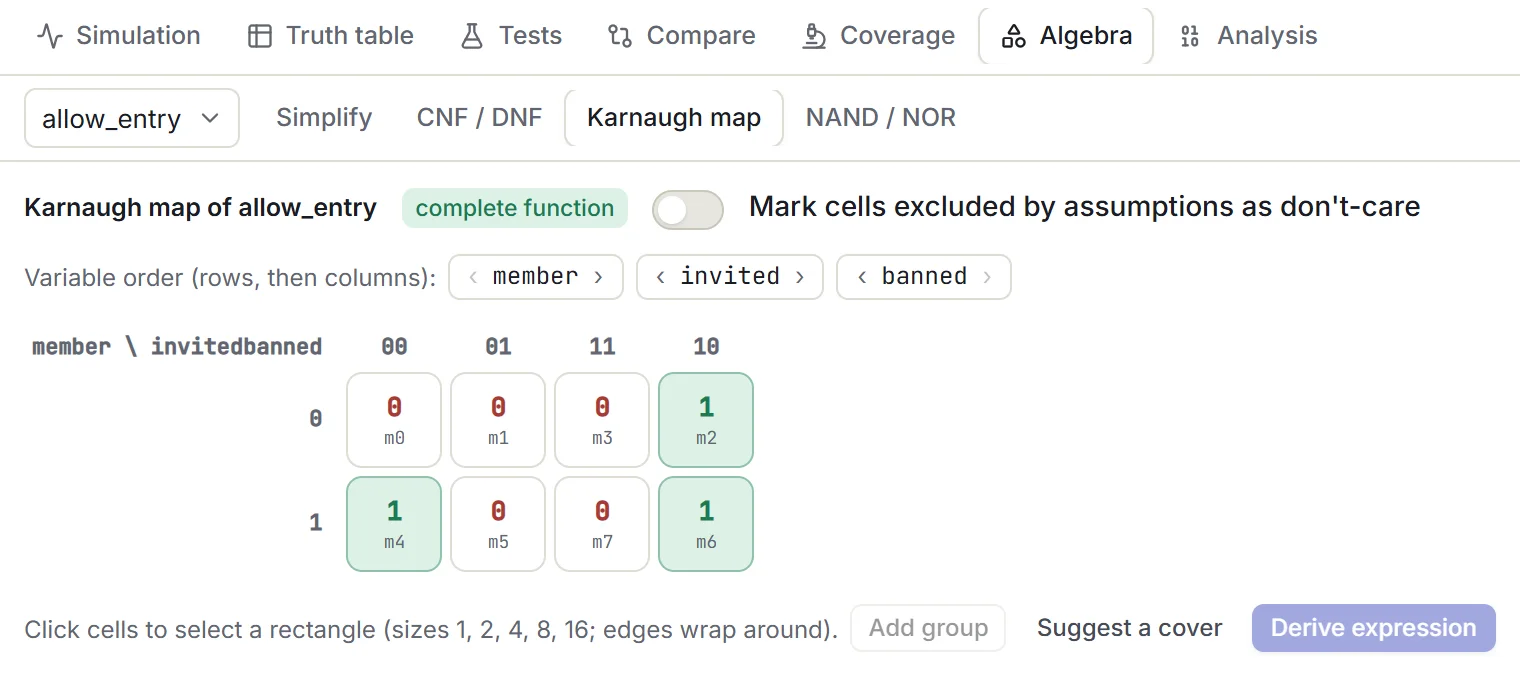
History
Not a Git wrapper: native history that understands rules. A commit captures the logic, wording, glossary, diagram, assumptions, tests, and shared notes together, so an old formula can never be paired with a newer diagram.
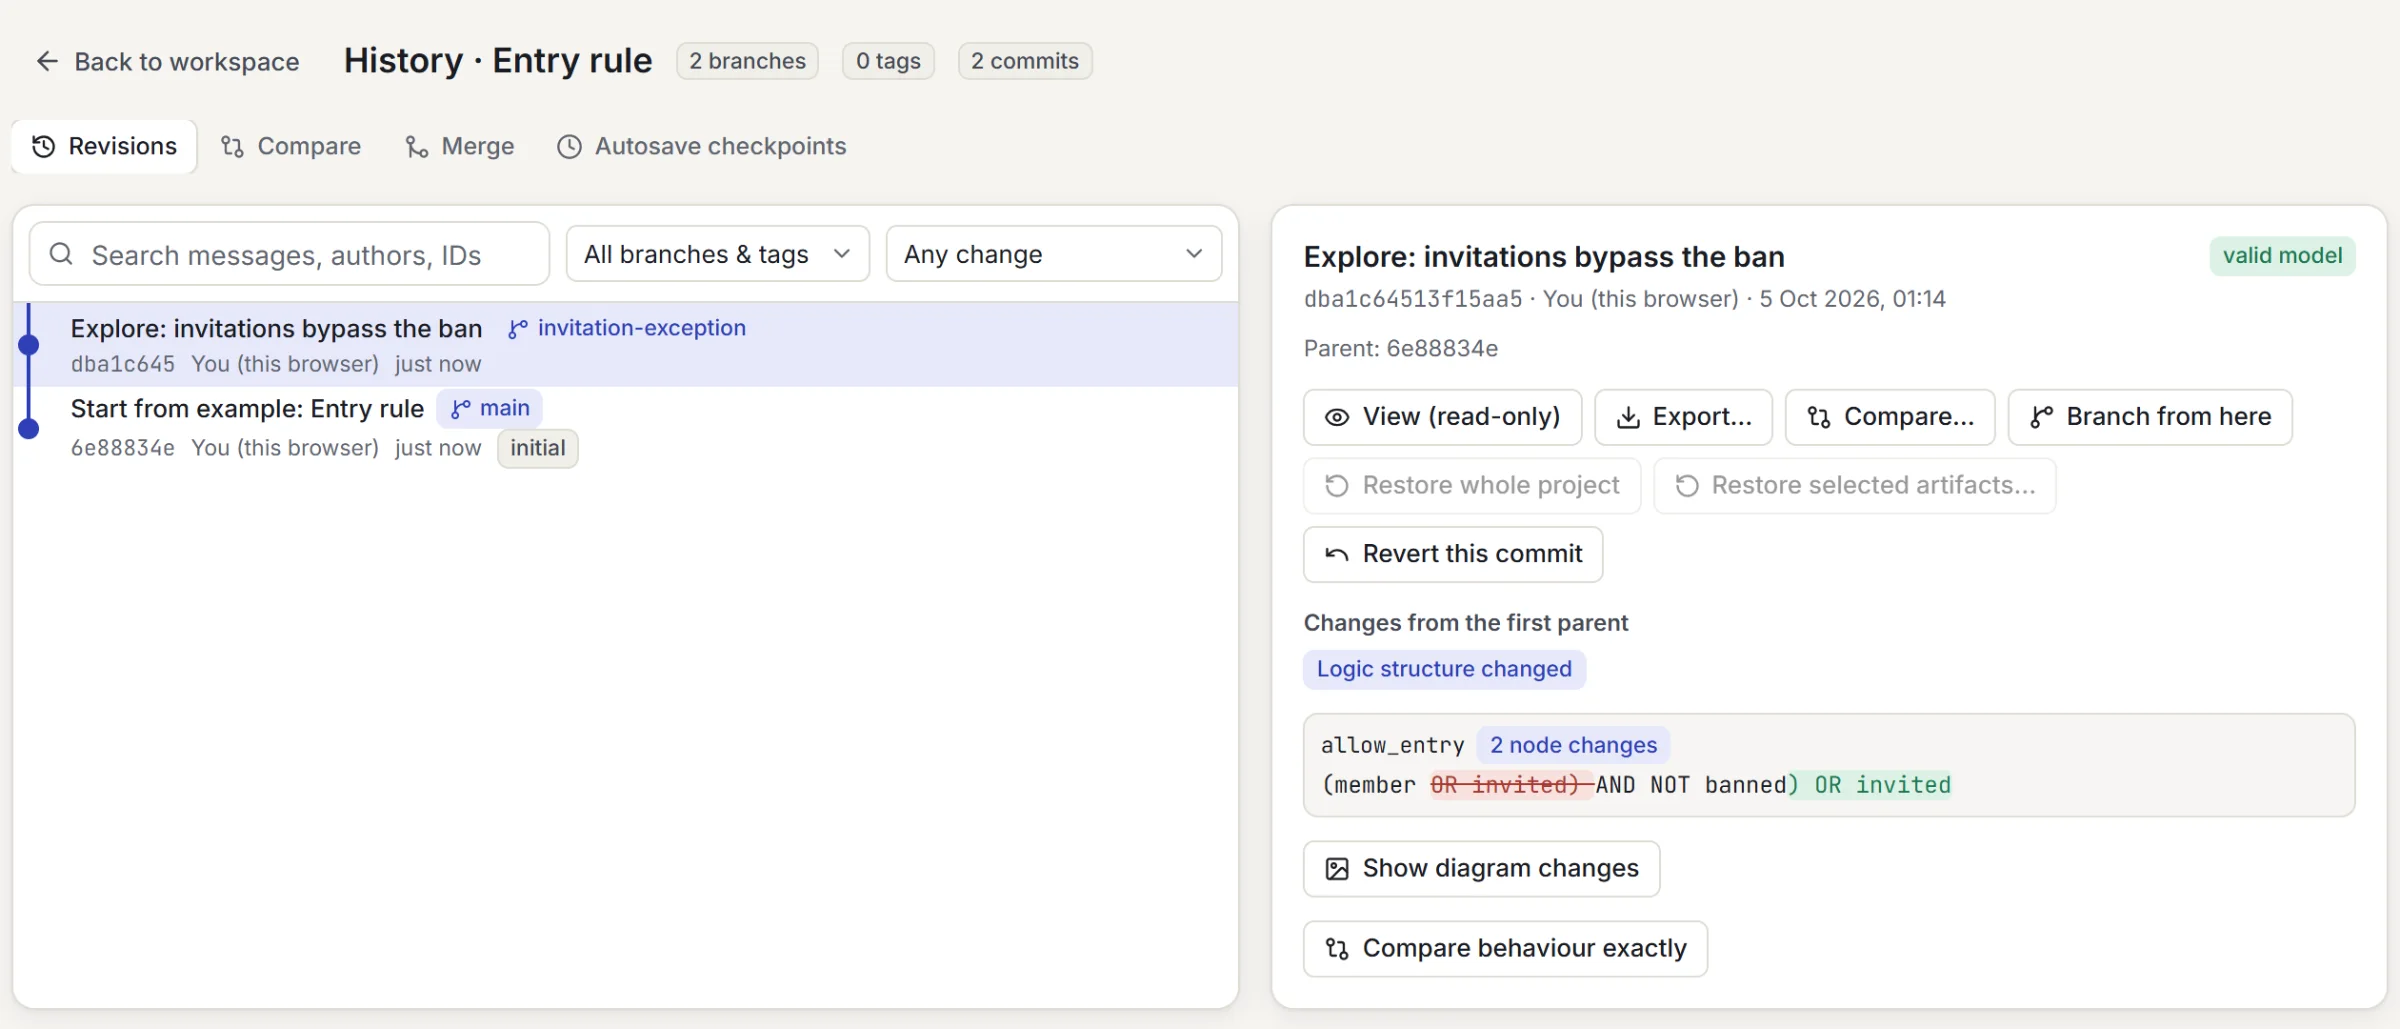
Explicit commits with messages, plus recoverable autosave checkpoints kept for 30 days, even for invalid drafts. Promote any checkpoint to a named commit.
Branch to explore an exception without touching the original. Tags name a fixed commit; an approved-baseline tag also requires current checks and a confirmed interpretation.
Text, structure, visual layout, and behaviour are compared separately. A formatting change, an equivalent refactor, a scope change, and a behaviour change each get their own label.
Compatible edits combine. Conflicting ones, such as changes to the same operator, connection, meaning, test expectation, or note, are shown for review. Relevant checks rerun before you commit the merge.
Open merge requests, require approval from an independent reviewer, and protect important branches with mandatory current checks. Rules are enforced on the server.
Restore a whole model or selected artifacts, with dependencies resolved first. A restore is always a new commit, and later comments and notes are never rolled back.
History, branches, and comparisons work offline in local models. No Git account or external repository is needed, and exported files are deterministic, so you can keep them in your own repository too.
Collaborate
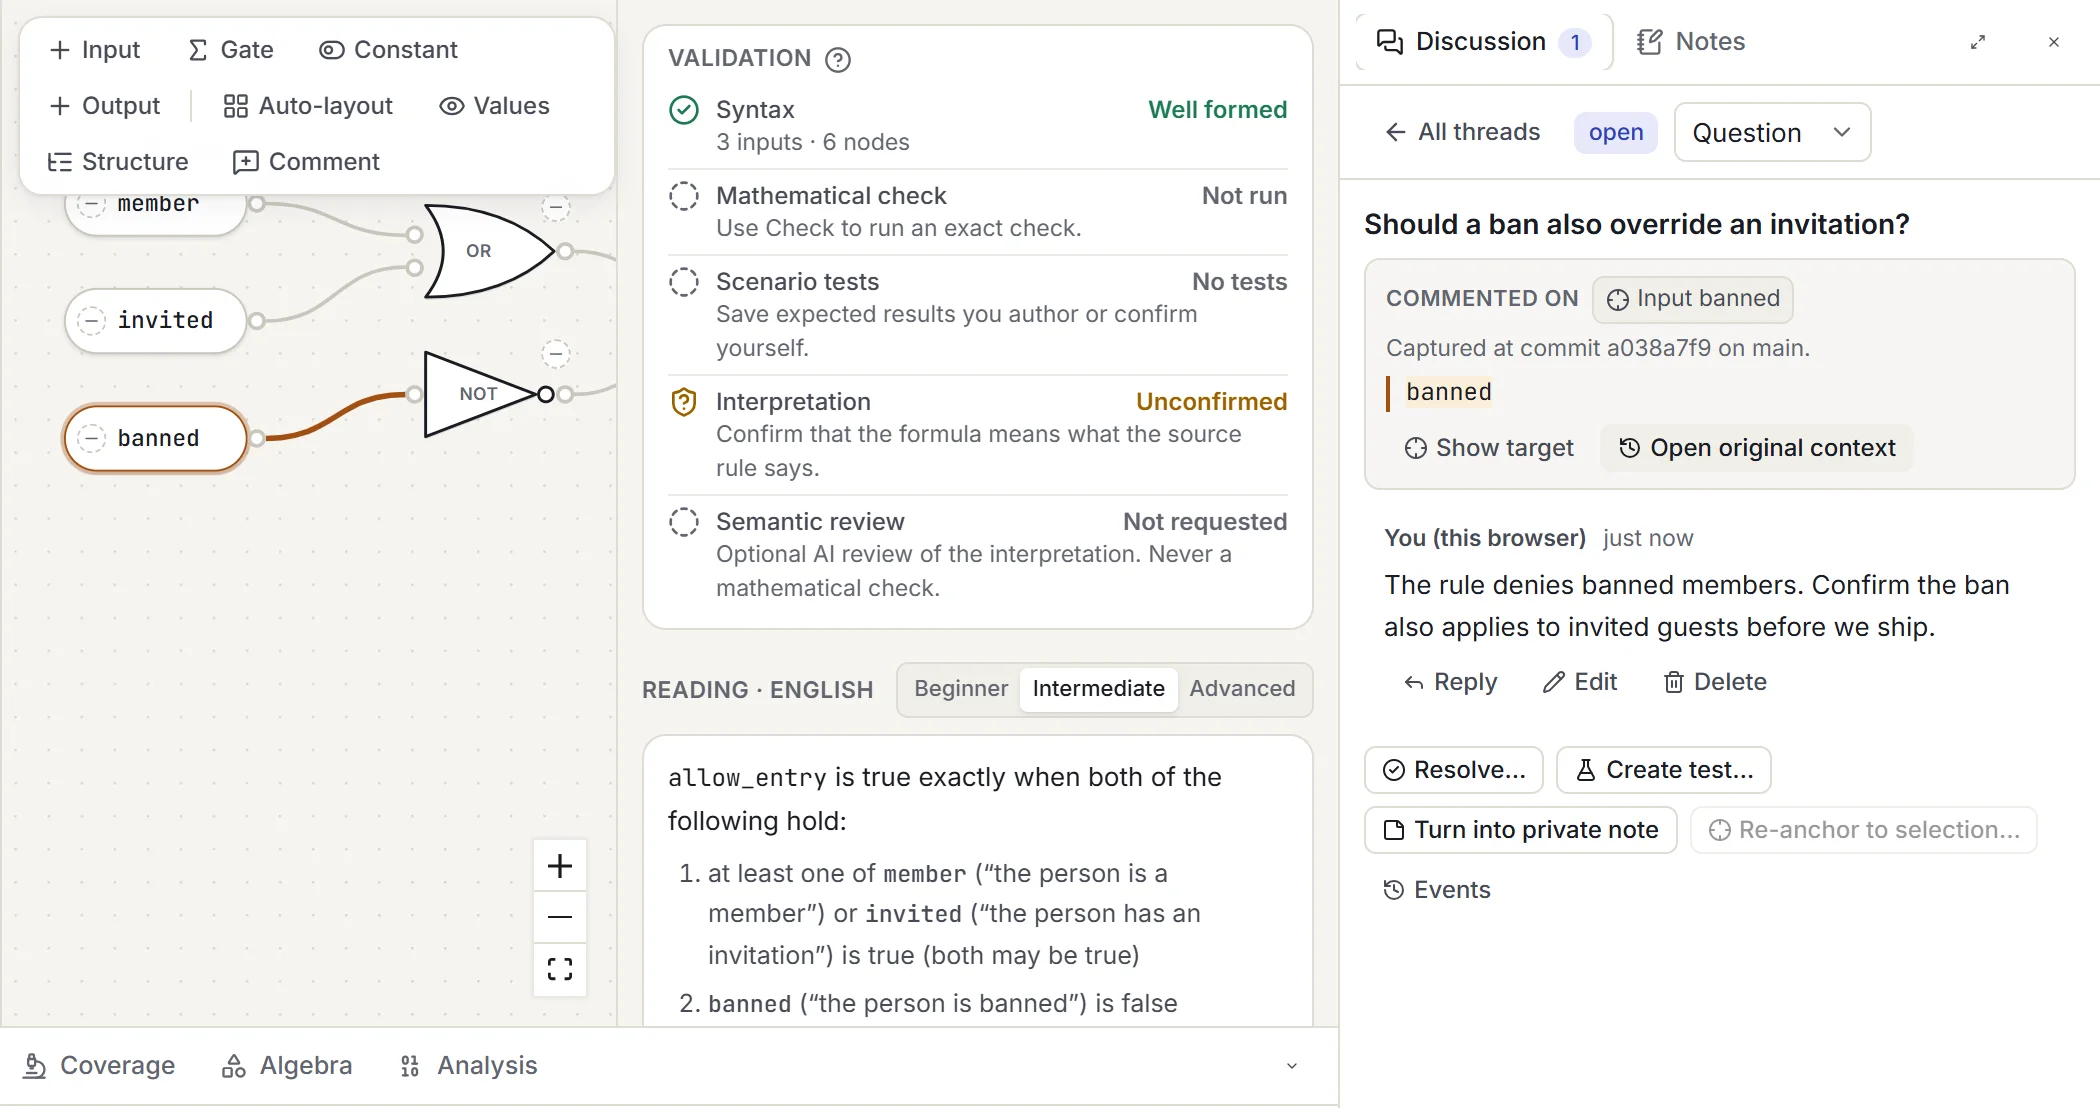
Comment on the exact thing you mean: a formula fragment, a gate, a clause, a test, or a revision. If the logic changes later, the comment says so instead of silently attaching itself to something new.
Sign in and copy a local model to your personal or team cloud. Edit offline and sync later; concurrent edits are kept side by side for an explicit merge, never overwritten.
Owner, admin, editor, commenter, and viewer. Commenters can discuss but not edit logic; viewers can read. Private notes stay private, even from owners and admins.
Share a fixed, read-only snapshot that never follows later edits. Links are private until you grant access, and they can be revoked or set to expire.
Configure the optional AI review with your own questions and thresholds, covering omitted conditions, exception scope, or a reversed “only if”. Versioned, and never a substitute for confirmation.
Keep shared terms, synonyms, and confirmed domain assumptions in one versioned glossary. Changing a term withdraws the approvals that depended on it.
Publish subcircuits, categories with their value lists, scales, and scale mappings to a team library. Models stay pinned to the version they use until someone reviews and approves the upgrade.
Export
Export a single artifact, a selection, or everything from one pinned revision, so a package can never mix an old formula with a newer diagram. Exports run in your browser, never call AI, and never change the model.
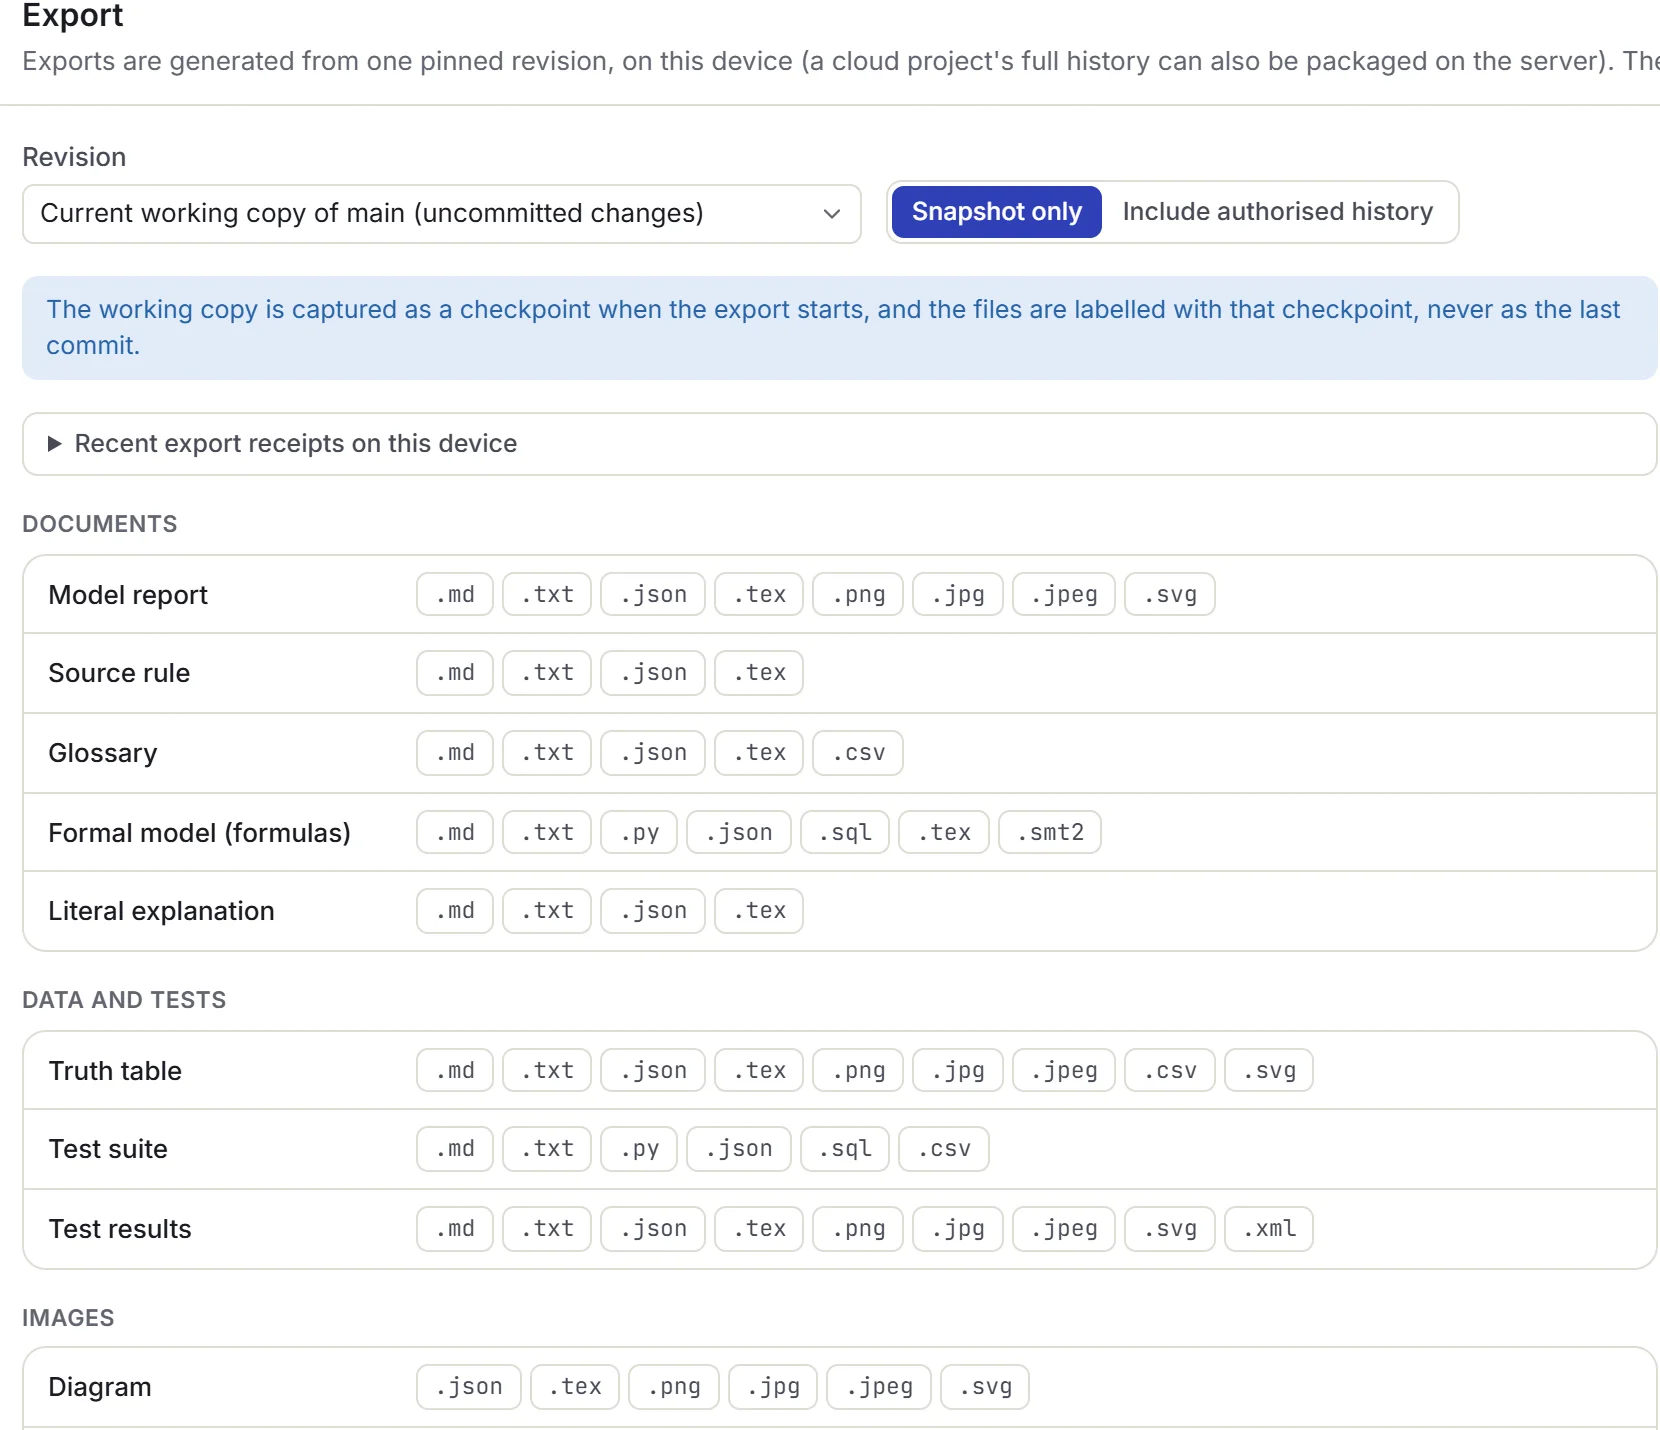
| Format | What you get |
|---|---|
.py | A readable Python 3 evaluator and a unittest suite, with strict Boolean input checks: strings, numbers, and None are rejected, never coerced. Thresholds, category values, scale levels, counts, and points are computed from the values you pass, undeclared values are rejected, and an outcome set returns its label. |
.sql | A PostgreSQL Boolean expression with a read-only SELECT and a VALUES test harness. Missing or NULL inputs are reported as invalid, never silently treated as FALSE. Counts and scores are sums of CASE expressions, and an outcome set is a CASE in table order. |
.smt2 | SMT-LIB Boolean definitions and scoped satisfiability queries, including completeness, exclusivity, strictness, and monotonicity, with each sat / unsat outcome explained. |
.tex | LaTeX fragments or standalone reports: formulas, truth tables, decision tables, algebra steps, and TikZ diagrams and Karnaugh maps, count and score gates included. |
.md · .txt | Readable reports: source rules, explanations, glossary, tests and results, transformations, comments, and notes. Also the text form of a strictness map, a Venn diagram, or a mapping diagram. |
.json | The lossless native format: a model snapshot or a full-history package you can import again. Also the result behind a strictness map, a Venn diagram, or a mapping diagram. |
.png · .jpg · .jpeg · .svg | Gate diagrams, truth-table pages, Karnaugh maps, strictness maps, Venn diagrams, mapping diagrams, and report cards, at the size, scale, and theme you choose, with real JPEG data under either extension. |
.csv · .xml | Truth tables and scenario suites as CSV, with spreadsheet-formula injection neutralised; JUnit-compatible XML test reports. |
Generated Python, SQL, and SMT-LIB are produced from tested templates, never by AI, and are cross-checked against the engine on thousands of generated models before every release. Exporting code does not run it.
API
A documented, versioned API and an MCP server answer with the same engine as the app: the same verdicts, the same replayed cases, the same limits. A program acts for a person, within the scopes that person gave it and the role that person holds. Both are on every plan.
Create a token in your account settings for a script or a CI job. Give it only the scopes it needs, limit it to named teams or models, and revoke it at any time. Every token expires, after 90 days by default and a year at most, and Tangibool stores only its hash.
Version 1 is a documented contract with an OpenAPI specification. Create a model from rule text kept in your repository, run exact checks and saved tests, and collect results and exports. A verdict is holds, violated, or unknown, never an HTTP error.
Send edits as a change set: add an input, change a formula, add a test. A dry run returns the diagnostics, the resulting outline, and the behaviour comparison, and stores nothing. A commit moves the branch only if nobody else has moved it in the meantime.
Send logic with the request to parse it, evaluate a case, check a property, compare two rules, page through a truth table, ask why a case got its result, or generate code. The server analyses it in memory and never stores or logs it.
Connect an assistant and approve, in the app, what it may read and do. It can check and compare rules, explain a result, and run saved tests, and the engine computes every result it reports. Its changes arrive as a proposal branch, with tests marked AI-proposed, for you to review and merge.
Have your own systems told when a branch moves, a tag is created, a merge request is opened, merged, or closed, a run or an export finishes, or a discussion starts. Deliveries are signed, retried for up to 24 hours, and carry no model content.
Whatever its scopes, a program can never confirm what a rule means, confirm a test’s expected result, approve a merge request, or create an approved baseline. Those acts stay with a person in the app, and the server refuses a request that attempts one.
curl -sS -X POST \
  "https://api.tangibool.com/v1/logic/check" \
  -H "Authorization: Bearer $TANGIBOOL_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "logic": { "text": {
      "inputs": [{ "name": "a" }, { "name": "b" }],
      "formulas": [
        { "name": "both", "text": "a AND b" }
      ]
    } },
    "query": { "kind": "satisfiable",
               "formula": "both" }
  }'
The answer carries the verdict, a replayed case, and the digest and engine versions it is bound to.
Learn
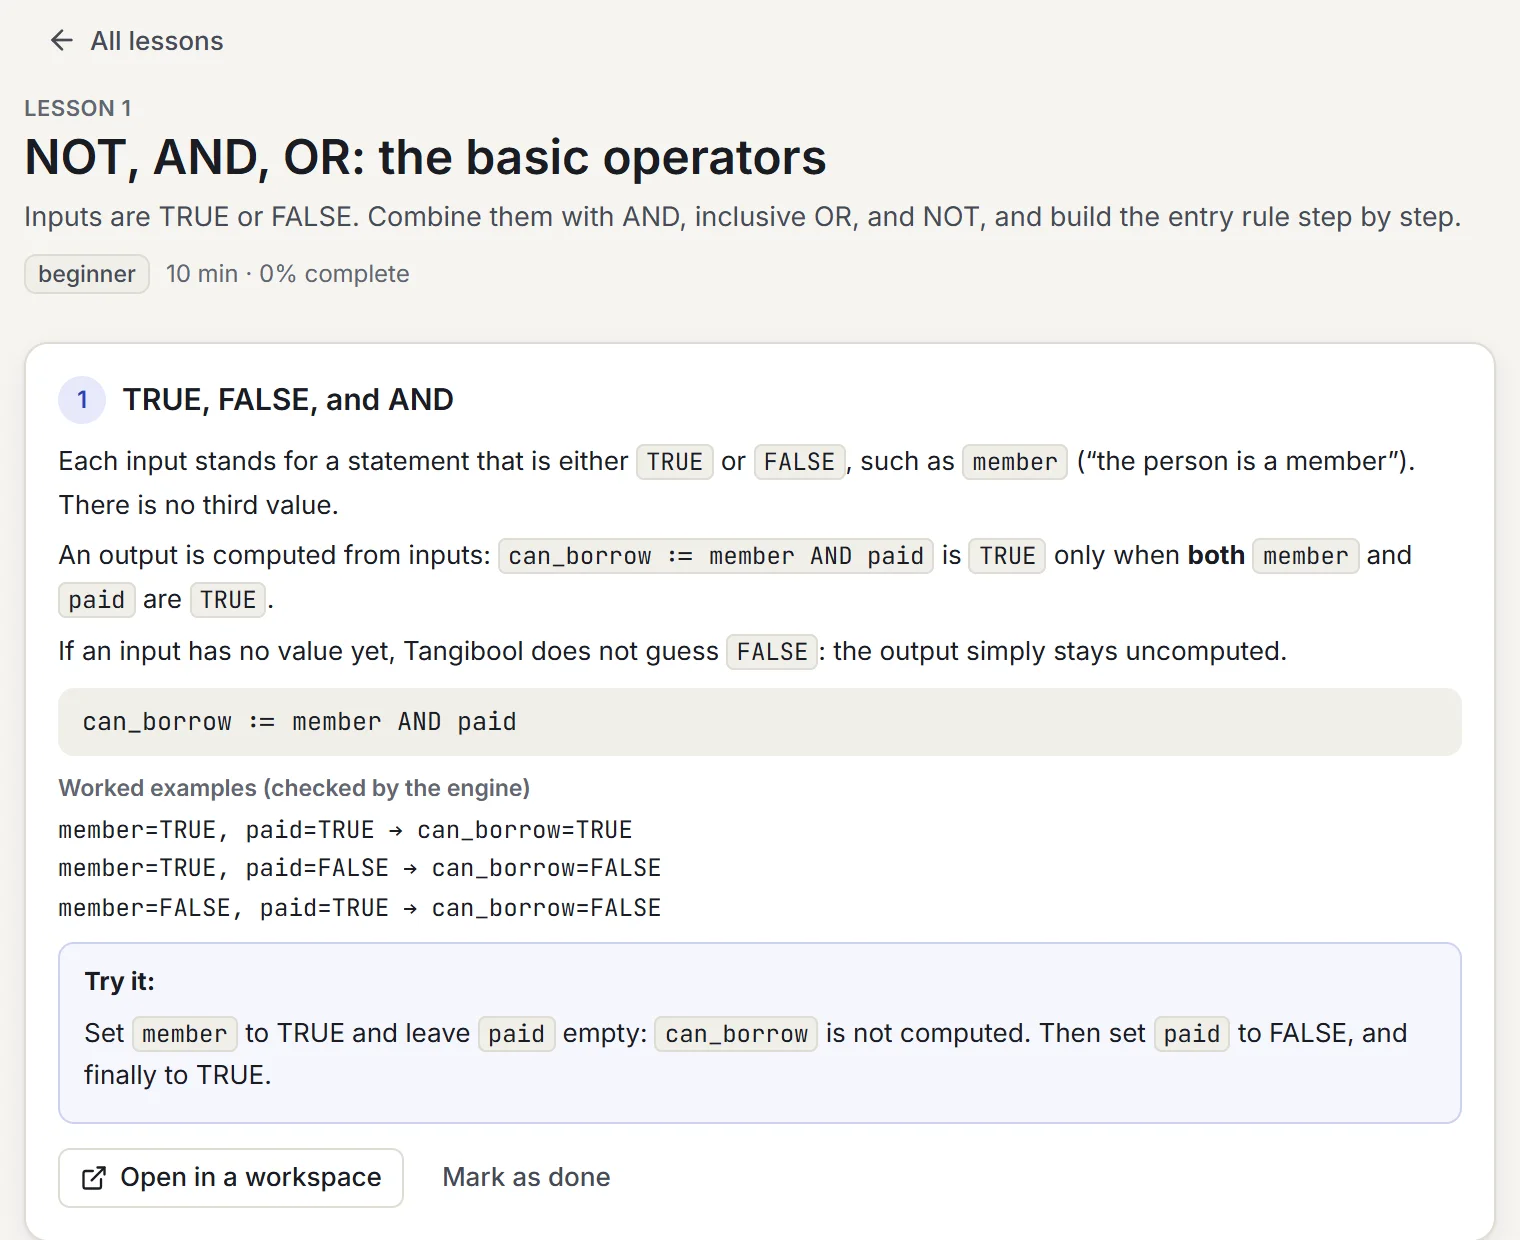
Every lesson opens real workspace models checked by the same engine, not disconnected illustrations. Exercises give concrete feedback with replayable scenarios, in all four content languages. Progress is saved on your device, and in your account when you sign in.
Honest by design
Trust comes from saying exactly what was checked, and what wasn’t. These rules are built into every result, report, and export.
A check that exceeds its budget says “Not determined”. It never turns into a green tick, and a list of ways to qualify or a strictness map that ran out of budget is labelled partial.
Change the logic, assumptions, or tests and earlier results say which revision they belong to and can’t be applied.
An argument whose premises contradict each other is “valid” only vacuously, and you’re told so prominently.
Unsatisfiable results are labelled “solver-checked”. Tangibool doesn’t claim independently verified proof certificates.
A simplification is better by the objective you chose, such as fewer operators, and a reason for a result is irreducible: no fact can be removed, other reasons may exist. Neither is ever called “the smallest possible”.
Structural coverage and mutation scores measure your tests. They’re never presented as proof the rule is right.
No AI confidence is ever shown as a mathematical guarantee, and no AI output is accepted without you. An assistant connected through the API can propose a change, but it cannot confirm, approve, or merge it.
Tangibool verifies the model you supply, not the real-world truth, legality, completeness, or safety of a policy.
Operating limits
These bounds keep every operation fast and exact. They apply to every plan and describe supported sizes, not features you have to unlock. Anything beyond them fails clearly instead of returning a partial result dressed up as a complete one. The API’s request and compute allowances are the one exception: they grow with the plan and are listed on the pricing page.
Tangibool works with two-valued Boolean logic and propositional logic. Numbers, categories, scales, counts, and scores enter through inputs defined outside the formulas, such as age_at_least_18 for age ≥ 18 or plan IN Paid, and compile to TRUE/FALSE inputs whose relationships are derived exactly. It does not do arithmetic beyond a count or a points total, compare two different quantities except on one ordered scale, evaluate text, dates, or units, or quantify over collections such as order lines or portfolio holdings.
| What | Limit |
|---|---|
| Distinct inputs per model | 64 |
| Written outputs · premises · assumptions per model | 64 each |
| Expression nodes (after expanding subcircuits) | 500 |
| Nesting depth | 64 |
| Categories per model · values per category · value lists | 64 · 2,000 · 500 |
| Value-list hierarchy depth | 16 |
| Ordered scales per model · levels per scale · outside values | 64 · 100 · 8 |
| Counting constraint operands | 2–64 |
| Points tables per model · rows per table · points per row | 32 · 64 · −1,000 to 1,000 |
| Outcome sets per model · labels per set | 32 · 32 |
| Decision table | 500 rows · 64 columns |
| Membership tests per set-valued input | 12 |
| Truth table, automatic | 8 inputs · 256 rows |
| Truth table, on request | 12 inputs · 4,096 rows |
| Karnaugh maps | 0–4 inputs |
| CNF / DNF size | 4,096 clauses · 20,000 literals |
| Mutation run | 500 mutants · 30 s |
| Server solver budget (default) | 2 s per query |
| Why-a-result and strictness analyses | 10 s per operation |
| Ways to qualify listed | 200 |
| Smallest changes | distance up to 4 · 50 listed |
| Strictness map | 12 rules |
| Venn diagram | 2 or 3 lists or rules |
| Saved tests per model | 1,000 |
| Natural-language drafting request | 4,000 characters |
| Note · comment | 50,000 · 10,000 characters |
| Export archive | 100 MiB · 10,000 files |
| Images | 8,192 px per edge · 32 MP |
| Personal access tokens per user | 50 active |
| Token lifetime | 90 days by default · 1 year at most |
| Edits in one change set | 500 |
| Webhooks | 10 per model · 25 per team |
FAQ
No. Open the app and start working: models, history, tests, notes, lessons, and exports all work signed out, stored in your browser. Sign in when you want cloud sync, teams, sharing, merge requests, AI drafting, or the API. Browser storage is not a cloud backup, so export or copy important models to the cloud.
Never. AI can draft a formula from your words, suggest clarifications, paraphrase an explanation, or review a draft for likely omissions. Every mathematical result comes from the deterministic engine, and only you can confirm what a rule is meant to say. You can switch AI off entirely and keep every deterministic feature.
For larger models Tangibool runs a bounded SAT query on the server, but only after telling you that the model will be sent. If the query finishes, you get an exact answer; if it runs out of budget, the result is “Not determined”. It never presents a sample of scenarios as a complete check.
Yes, through threshold inputs. A condition like “age is at least 18” becomes the input age_at_least_18, defined as age ≥ 18 on the quantity age. The formula keeps using a TRUE/FALSE input, a scenario or a saved test can give the number itself, which decides every threshold on that quantity by exact comparison, and the ordering between thresholds is derived for you: anyone aged 25 or more is aged 21 or more. The same pattern covers category values (plan IN Paid), levels on an ordered scale (rating ≥ BBB-), counts of conditions, and points totals. Tangibool does no other arithmetic, and it never infers that “premium member” implies “member” unless you add that assumption.
Yes. An outcome set names its outcomes in order, such as Approve, Refer, and Decline, and defines them as one condition per outcome, as a rule list where the first match wins, or as a decision table with the hit policy Unique, Any, First, or Priority. Each outcome compiles to a Boolean output, so every exact check still applies, and the engine checks that each admissible case gets exactly one outcome, reporting gaps, overlaps, and rows that can never apply with a replayed case for each.
Yes. Put both rules in one model, or compare two revisions or two branches, and ask whether one is at least as strict as the other: every case the stricter rule allows, the looser rule allows too. The answer is equivalent, at least as strict, looser, or incomparable, with a replayed case for each direction that fails. A strictness map orders up to twelve rules at once, rule layers such as regulation, prospectus, mandate, and internal limit are checked in order, and the same checks run as property tests in continuous integration.
Yes. Run the headless tangibool runner on a native JSON package you exported, or on a cloud model that it reads through the API with a token. Either way it uses the same engine as the browser and computes on your machine. It writes JSON and JUnit-compatible reports and exits with 0 only when at least one applicable test ran and all of them passed, 1 when an assertion failed, and 2 for invalid or inconclusive input. You can also start a test run through the API and read its result.
Yes. A documented, versioned API lets your own programs create and change models, run exact checks and saved tests, and fetch results and exports, with a personal access token that you create in your account settings. It is included on every plan; plans differ in how many requests and how much server compute you get. The developer docs have the guide, the reference, and the OpenAPI specification.
Yes, through the MCP server. You connect the assistant and approve, in the app, what it may read and do. It can check and compare rules, explain why a case got its result, run saved tests, and propose changes, and the engine computes every result it reports. Its proposals arrive on a branch of their own, with tests marked AI-proposed. It can never confirm what a rule means, approve a merge request, or merge: those stay with you.
For your rules, it doesn’t need it: commits, branches, tags, diffs, merges, and restores are built in and understand logic, diagrams, and tests. Because exports are deterministic, you can still keep the generated files in your own Git repository if you like.
It is designed to the WCAG 2.2 AA standard. Every diagram action has a keyboard alternative, a structured view sits alongside the canvas, controls are labelled for screen readers, and truth values always use an icon and a word, never colour alone. Automated WCAG 2.2 accessibility scans of the main pages and dialogs are part of the test suite, in both light and dark themes.
Current versions of Chrome, Edge, Firefox, and Safari. Tangibool is desktop-first, and on tablets and phones the same features are arranged in tabs rather than squeezed onto one screen.
Paste a condition from your codebase or a sentence from a policy, and find out exactly what it does.